Nominal Dropout Rate
Indicator UD 2.7
PAHO/CIM
April 22, 2025
Source:vignettes/articles/en/nominal_dropout_en.Rmd
nominal_dropout_en.RmdRationale
The dropout rate is an indicator used to evaluate the loss of follow-up in vaccination schedules. It reflects the percentage of individuals who did not receive a final dose (i.e., DTP3) among those who received an initial dose (i.e., DTP1). In aggregated systems, it is estimated using the following formula:
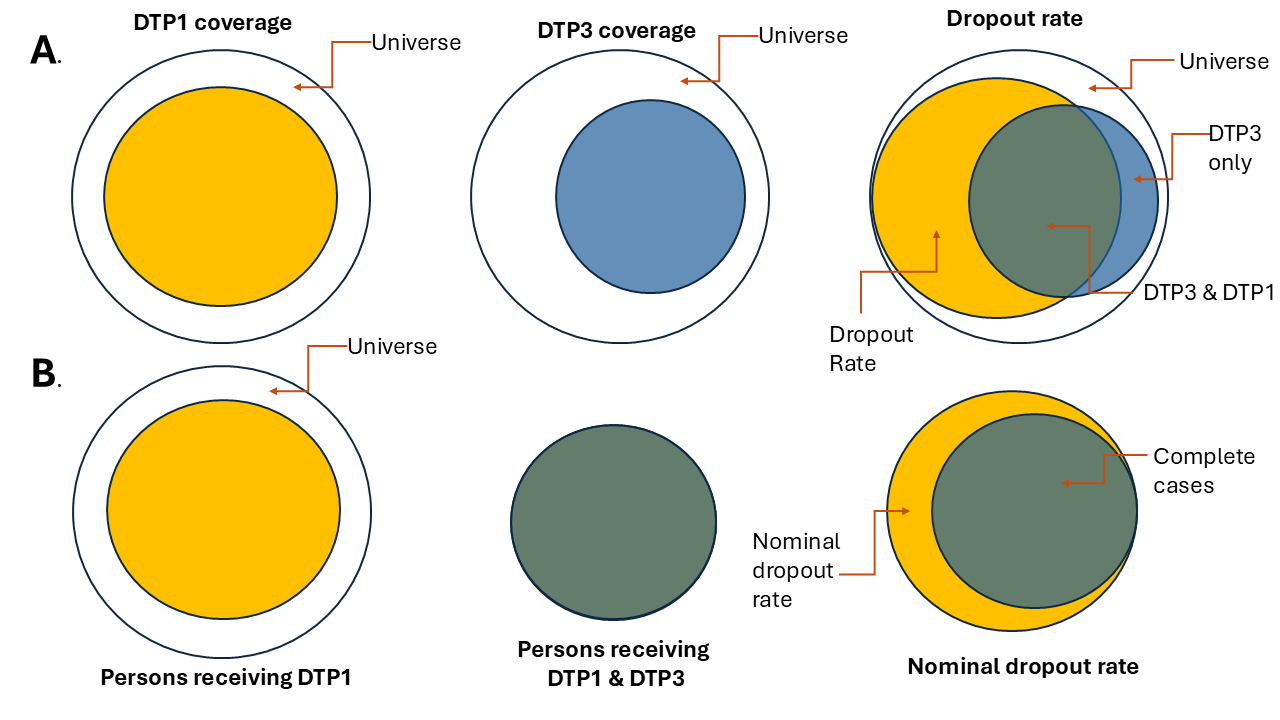
Performing the analysis with aggregated data does not guarantee that the individuals who received both doses are the same, as shown in Figure 1A. Electronic nominal vaccination records enable a person-to-person analysis, ensuring that the individuals who received both doses are indeed the same, as illustrated in Figure 1B.
Note
All functions used for nominal dropout analyses within immunABC begin with the
nod_prefix.
Glossary
Political Geographic Boundaries
Throughout this vignette, we will make reference to different levels of political geographic boundaries. These levels are defined by the country/territory and can have different names from country to country. immunABC is agnostic to these names and requires the user to recode their variable names to fit the immunABC structure.
Namely, immunABC can distinguish three administrative levels, which listed from top to bottom level are: ADM0, ADM1 and ADM2.
- ADM0: The country. This is the top-most administrative level.
- ADM1: The first geographic subdivision in the country. ADM0 contains several ADM1 subdivisions.
- ADM2: The second geographic subdivision in the country. Each ADM1 contains several ADM2 subdivisions.
Vaccine Names
Our example datasets use a specific naming convention for the vaccine doses. This might not match your own naming schemes, but it will not affect the usage of the package as long as you make sure to be consistent when naming vaccine doses.
For example, the vaccine names used in the immunABC package are:
| Abbreviation | Full Name |
|---|---|
| SRP1 | Measles, Rubella, and Mumps Vaccine (1st dose) |
| DTP1 | Diphtheria, Tetanus, and Pertussis Vaccine (1st dose) |
| DTP2 | Diphtheria, Tetanus, and Pertussis Vaccine (2nd dose) |
| DTP3 | Diphtheria, Tetanus, and Pertussis Vaccine (3rd dose) |
| BCG RN | Bacillus Calmette–Guérin Vaccine (at birth) |
| YFV1 | Yellow Fever Vaccine (1st dose) |
Usage
Install Package
The first step to run the nominal dropout rate analysis is to install the immunABC package available on Github
devtools::install_github("IM-Data-PAHO/immunabc")Load Data
The functions in this module require you to provide your EIR dataset in a specific format.
To make it easy for you to test out immunABC’s functionality and understand the structure we require for your datasets, we will now explore the example dataset provided by immunABC that is required by this module.
EIR
The immunabc::immunABC.EIR data frame provides a
simulated, nominal-level table representing individual vaccination
events from an Electronic Immunization Registry (EIR). Each row
corresponds to a single vaccination act for a person, including
information on their residence, where they were vaccinated (occurrence),
their date of birth, and the vaccine dose received.
immunABC.EIR %>% head() %>% kable(caption = "Example Electronic Immunization Registry")| ID | date_birth | date_vax | ADM1_residence | ADM2_residence | ADM1_occurrence | ADM2_occurrence | dose |
|---|---|---|---|---|---|---|---|
| 191997 | 2023-08-08 | 2023-12-26 | ADM1_4 | ADM2_4_35 | ADM1_4 | ADM2_4_35 | DTP2 |
| 212189 | 2023-12-20 | 2023-12-26 | ADM1_5 | ADM2_5_61 | ADM1_5 | ADM2_5_61 | BCG RN |
| 118063 | 2022-09-15 | 2023-12-26 | ADM1_2 | ADM2_2_5 | ADM1_2 | ADM2_2_5 | DTP1 |
| 118063 | 2022-09-15 | 2023-12-26 | ADM1_2 | ADM2_2_5 | ADM1_2 | ADM2_2_5 | YFV1 |
| 130751 | 2022-10-27 | 2023-12-12 | ADM1_5 | ADM2_5_55 | ADM1_5 | ADM2_5_55 | YFV1 |
| 136532 | 2021-09-21 | 2023-12-26 | ADM1_3 | ADM2_3_12 | ADM1_3 | ADM2_3_12 | SRP1 |
-
ID: Unique person identification number. -
date_birth: Date of birth of person. -
date_vax: Date of vaccination event. - ADM1: Refers to the first geographic administrative level of the country.
- ADM2: Refers to the second geographic administrative level of the country.
- Residence: Refers to the place where the person lives.
- Occurrence: Refers to the place where the vaccination event
occurred.
-
dose: A combined variable representing the vaccine type and its corresponding dose number. For example, DTP1 refers to the first dose of a vaccine containing diphtheria, tetanus, and pertussis components.
Nominal Dropout Analysis
immunABC includes the functionality to estimate the nominal dropout rate, on a per-person basis. This allows for the analysis of any pair of doses by specifying an initial dose and a final dose. For correct interpretation, the initial dose must precede the final dose in the vaccination schedule, for example: DTP1 – DTP3 or DTP1 – MCV1. Additionally, it allows users to select the level of aggregation for the results, which can be at the national level or subnational levels (ADM1 or ADM2).
Expected workflow
The nod_dropout() and nod_barplot()
functions work together to perform nominal dropout analysis and
visualization. The nod_dropout() function computes the
nominal dropout and complete cases by residence across selected
administrative levels, birth cohorts, and vaccines. Its output (a data
table) is structured to be directly compatible with
nod_barplot(), which generates a visualization for the data
computed.

Example
Here is a simple use case of the nod_dropout() function,
where we compute nominal dropout for ADM 1 for DTP1 and DTP3 in our
example dataset.
#Runs the nominal dropout function
example_dropout <- nod_dropout(data.EIR = immunABC.EIR,
                               vaccine_init = "DTP1", #Starting vaccine based on your dataset
                               vaccine_end= "DTP3", #Ending vaccine based on your dataset
                               geo_level = "ADM1", #Can be ADM0, ADM1 or ADM2
                               birth_cohorts = NULL #Can be a vector of years or a year
                               )

# show results in table
example_dropout %>%
kable(digits = 3, caption = "Nominal dropout rate between DTP1 and DTP3 by ADM1 level")| ADM1_residence | indicator | num | denom | percent |
|---|---|---|---|---|
| ADM1_1 | complete | 1491 | 2607 | 57.192 |
| ADM1_1 | dropout | 1116 | 2607 | 42.808 |
| ADM1_2 | complete | 6967 | 12429 | 56.054 |
| ADM1_2 | dropout | 5462 | 12429 | 43.946 |
| ADM1_3 | complete | 30999 | 55608 | 55.746 |
| ADM1_3 | dropout | 24609 | 55608 | 44.254 |
| ADM1_4 | complete | 5304 | 7574 | 70.029 |
| ADM1_4 | dropout | 2270 | 7574 | 29.971 |
| ADM1_5 | complete | 2703 | 4040 | 66.906 |
| ADM1_5 | dropout | 1337 | 4040 | 33.094 |
Parameters accepted
-
data.EIR: R Structured dataframe with the variables listed above.
-
vaccine_init: The name (string) of the vaccine to use as the start point of the analysis as stored in the dose column of the dataframe.
-
vaccine_end: The name (string) of the vaccine to use as the end point of the analysis as stored in the dose column of the dataframe.
-
geo_level: Administrative level to use, this is an optional parameter. Can be “ADM0”, “ADM1” or “ADM2” as strings. Defaults to “ADM0” if ignored. -
birth_cohorts: Parameter to segment the analysis based on the year of birth of the persons in the dataframe. It is based on thedate_birthcolumn in the dataframe and can be a single year or a vector of years. -
fix_residence: Logical, defaults toTRUE. Only relevant whengeo_levelis “ADM1” or “ADM2”. Controls what happens when a person’sADM1_residence/ADM2_residenceis not the same across all of their records (for example, if they moved between doses). See Handling residence inconsistencies below.
The data.EIR, vaccine_init,
vaccine_end parameters are mandatory.
geo_level, birth_cohorts and
fix_residence are optional and help to segment the data or
ensure accuracy for more precise analyses.
Check the documentation of the function using
?nod_dropout() in R for additional information.
Handling residence inconsistencies
At the ADM1 or ADM2 level, nod_dropout() needs to match
a person’s initial and final doses under a single residence group. If a
person’s registered residence is not the same on every record (e.g.,
they moved between their DTP1 and DTP3 doses, and the older record was
never updated), their doses would otherwise be split across two
different residence groups and each dose would incorrectly appear as an
incomplete schedule.
The fix_residence parameter controls how
nod_dropout() handles this:
-
fix_residence = TRUE(default): before computing dropout, all of a person’s records are corrected to the residence of their most recent vaccination, so their doses are correctly grouped together. -
fix_residence = FALSE: residence values are not modified. If inconsistencies are found,nod_dropout()stops with an error, since its results would be inaccurate. Resolve them manually beforehand, or setfix_residence = TRUE.
The example below constructs a small EIR where person
ID 1 moved from ADM1_1 to ADM1_2
between doses, to illustrate both cases.
residence_example <- tibble::tibble(
  ID = c(1, 1, 2, 2),
  dose = c("DTP1", "DTP3", "DTP1", "DTP3"),
  date_vax = as.Date(c("2020-01-01", "2020-06-01", "2020-01-01", "2020-06-01")),
  date_birth = as.Date(c("2019-12-01", "2019-12-01", "2019-11-01", "2019-11-01")),
  ADM1_residence = c("ADM1_1", "ADM1_2", "ADM1_1", "ADM1_1"),
  ADM2_residence = c("ADM2_1", "ADM2_2", "ADM2_1", "ADM2_1"),
  ADM1_occurrence = c("ADM1_1", "ADM1_2", "ADM1_1", "ADM1_1"),
  ADM2_occurrence = c("ADM2_1", "ADM2_2", "ADM2_1", "ADM2_1")
)

residence_example %>% kable(caption = "Example EIR: ID 1 moved from ADM1_1 to ADM1_2 between doses")| ID | dose | date_vax | date_birth | ADM1_residence | ADM2_residence | ADM1_occurrence | ADM2_occurrence |
|---|---|---|---|---|---|---|---|
| 1 | DTP1 | 2020-01-01 | 2019-12-01 | ADM1_1 | ADM2_1 | ADM1_1 | ADM2_1 |
| 1 | DTP3 | 2020-06-01 | 2019-12-01 | ADM1_2 | ADM2_2 | ADM1_2 | ADM2_2 |
| 2 | DTP1 | 2020-01-01 | 2019-11-01 | ADM1_1 | ADM2_1 | ADM1_1 | ADM2_1 |
| 2 | DTP3 | 2020-06-01 | 2019-11-01 | ADM1_1 | ADM2_1 | ADM1_1 | ADM2_1 |
With fix_residence = TRUE, ID 1’s records
are both reassigned to ADM1_2 (their most recent
residence), so they are correctly counted as complete:
fixed_result <- nod_dropout(
  data.EIR = residence_example,
  vaccine_init = "DTP1",
  vaccine_end = "DTP3",
  geo_level = "ADM1",
  fix_residence = TRUE
)
## Warning in .enforce_single_residence(data.EIR, fix_residence): 1 ID(s) have
## more than one place of residence across their records.## 1 record(s) updated to the residence of the most recent vaccination.
fixed_result %>% kable(digits = 3, caption = "Result with fix_residence = TRUE")| ADM1_residence | indicator | num | denom | percent |
|---|---|---|---|---|
| ADM1_1 | complete | 1 | 1 | 100 |
| ADM1_2 | complete | 1 | 1 | 100 |
With fix_residence = FALSE, ID 1’s two
doses would stay split between ADM1_1 and
ADM1_2, and nod_dropout() would incorrectly
report a dropout in both groups. To avoid this,
nod_dropout() stops with an error:
unfixed_result <- nod_dropout(
  data.EIR = residence_example,
  vaccine_init = "DTP1",
  vaccine_end = "DTP3",
  geo_level = "ADM1",
  fix_residence = FALSE
)
## Error in `.enforce_single_residence()`:
## ! Error: 1 ID(s) have more than one place of residence across their records. Correct them in data.EIR, or set fix_residence = TRUE to assign each person the residence of their most recent vaccination.This output may be fed directly into the nod_barplot()
function as shown below.
# Runs the nod_barplot function
example_dropout_plot <- nod_barplot(data=example_dropout, order="alpha")

#show plot
example_dropout_plot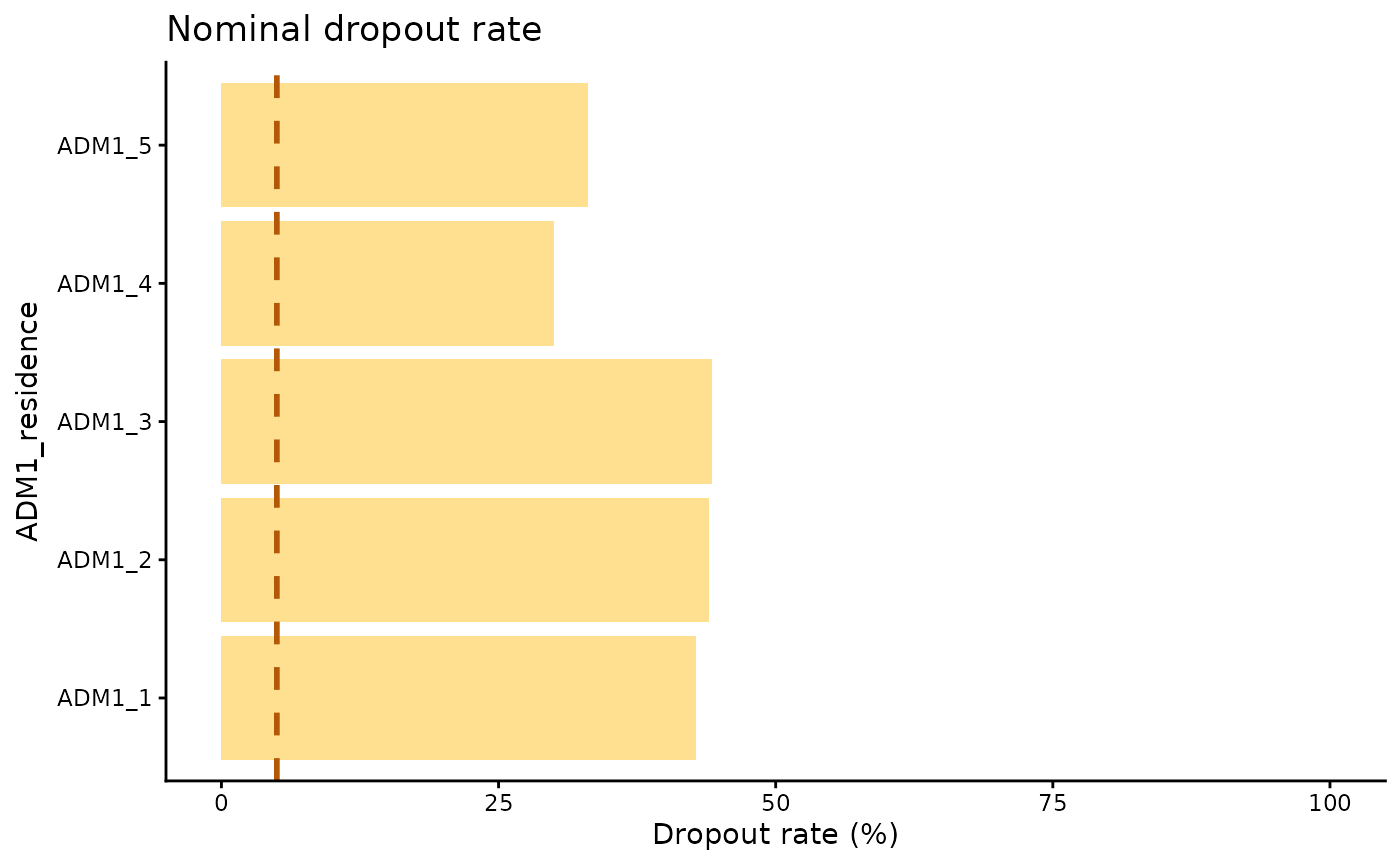
Parameters accepted
The function nod_barplot() accepts the following
parameters:
-
data: Dataframe formatted from the result of thenod_dropout()function. -
order: Organizes the bars based on three options: “alpha”, “desc” or “asc”, default is “alpha”. -
within_ADM1: Allows to filter within an ADM1 and display only the ADM2 data corresponding to the specified ADM1.
Interpretation
This chart shows the nominal dropout per Administrative level 1 as well as a 5% line to indicate a threshold of nominal dropout. Having a high dropout rate means a large percentage of the persons analyzed are not registering for the follow up doses of their schedule. Ideally, every person that has received a dose of a multi-dose schedule should return to receive the follow up dose. In this case the administrative level ADM1_1 is the one doing the worst, whilst the ADM1_4 is doing the best.
All of the administrative units have a nominal dropout rate above 25% meaning, at least 25% of the persons in that target group did not come back for their follow up dose.
Summary
Accurately monitoring continuity in multi-dose vaccination schedules is vital for immunisation programmes. The nominal dropout rate—the proportion of individuals who begin a series (e.g., DTP1) but fail to receive its final dose (e.g., DTP3)—offers a person-level view of programme performance that aggregated counts cannot. This vignette introduces immunABC, an R package that streamlines nominal dropout analysis by harnessing electronic immunisation registry (EIR) data.
After defining key concepts—administrative units (ADM0–2) and
standardised vaccine-dose codes—the document walks the reader through a
reproducible workflow: installing the package, exploring the bundled
example EIR, computing dropout with nod_dropout(), and
visualising results with nod_barplot(). A worked example
estimates DTP1→DTP3 dropout at the ADM1 level, revealing that every
subdivision exceeds the 25 % dropout threshold; ADM1_1 performs the
worst, while ADM1_4 performs the best relative to a 5 % target line.
By coupling granular EIR data with a transparent analytical pipeline, immunABC enables precise, geographically disaggregated insights into follow-up losses, equipping health authorities to target interventions where they are most needed.